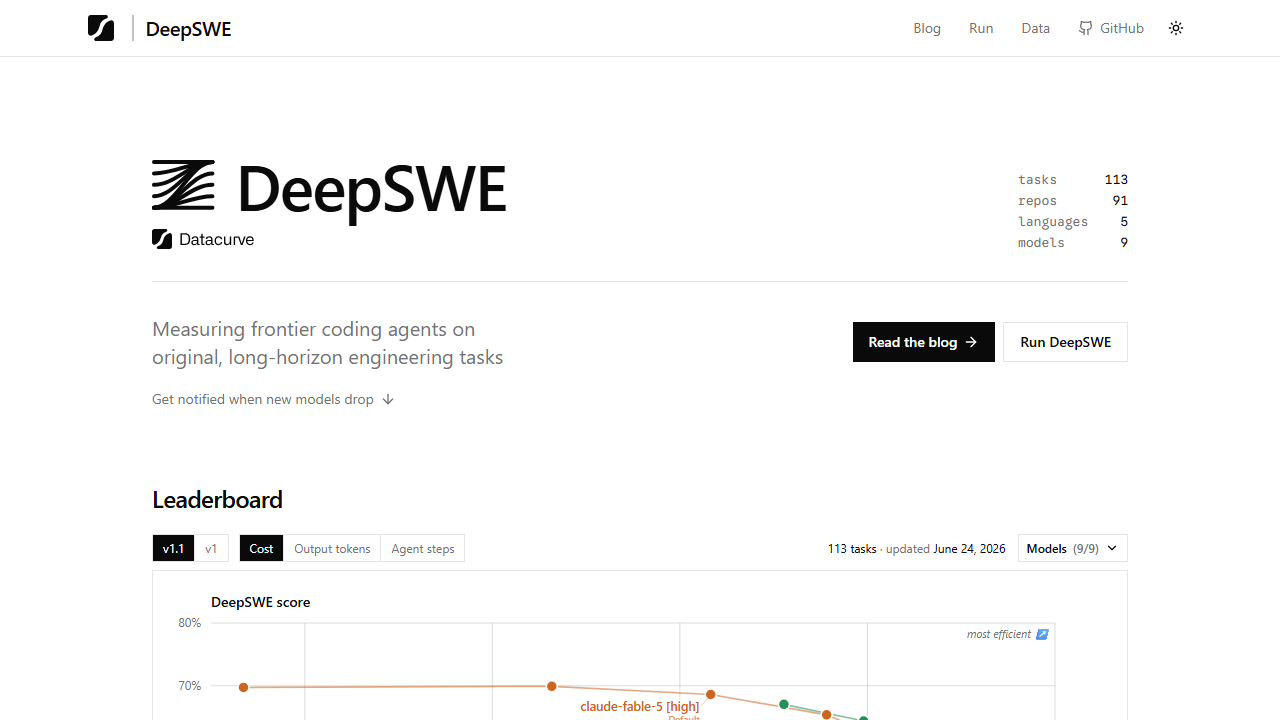
deepswe.datacurve.ai
DeepSWE
DeepSWE measures frontier coding agents on original, long-horizon software engineering tasks.
Visit deepswe.datacurve.ai ->
Only curated links
A handpicked collection of benchmark sites for comparing AI models, coding agents and real-world performance.
Benchmark
DeepSWE measures frontier coding agents on original, long-horizon software engineering tasks.
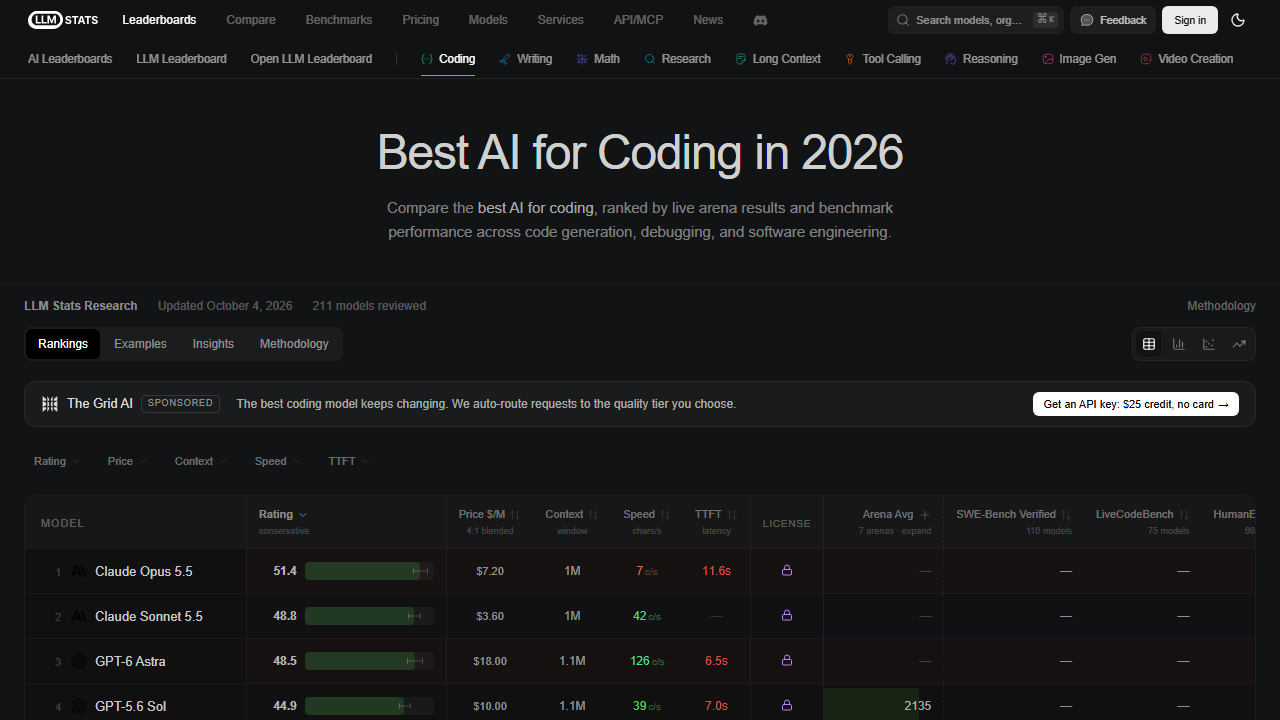
Compare the best AI for coding using live coding arena results, benchmark performance, and real generation examples for code generation, debugging, and software engineering.
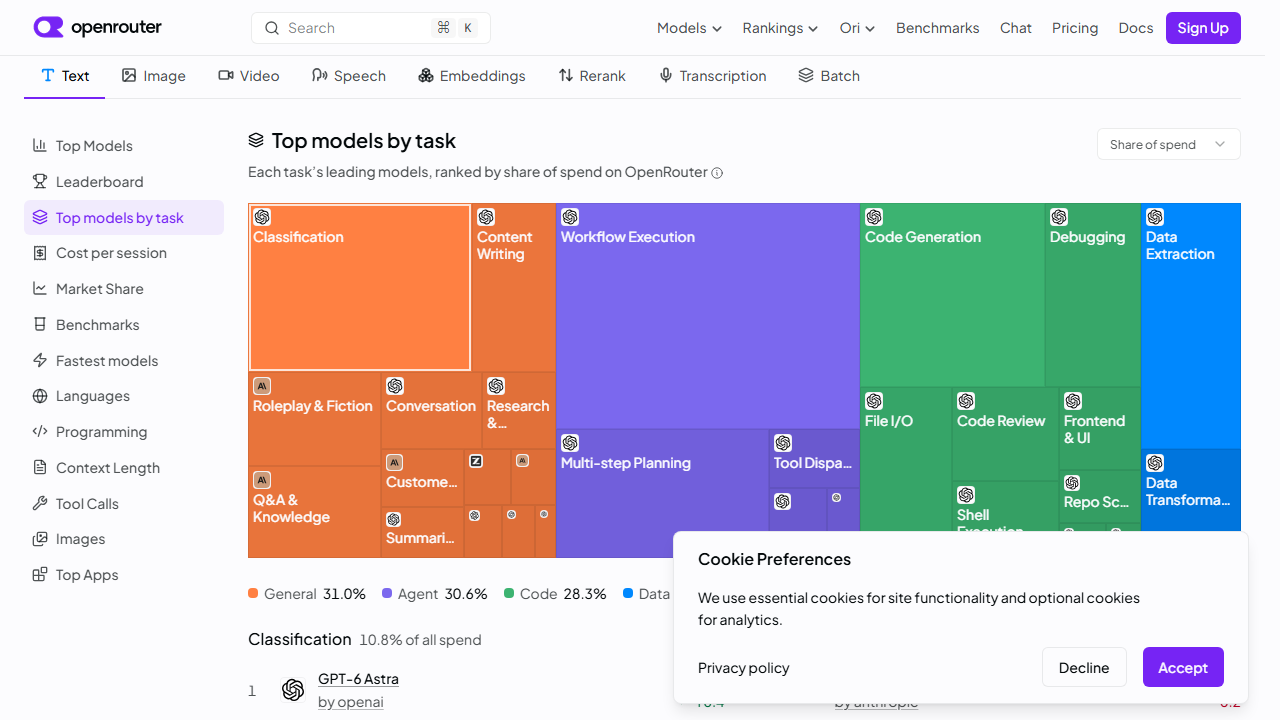
LLM rankings and AI leaderboard by real-world usage, ranked by tokens processed through the OpenRouter API. See which AI models developers actually use.
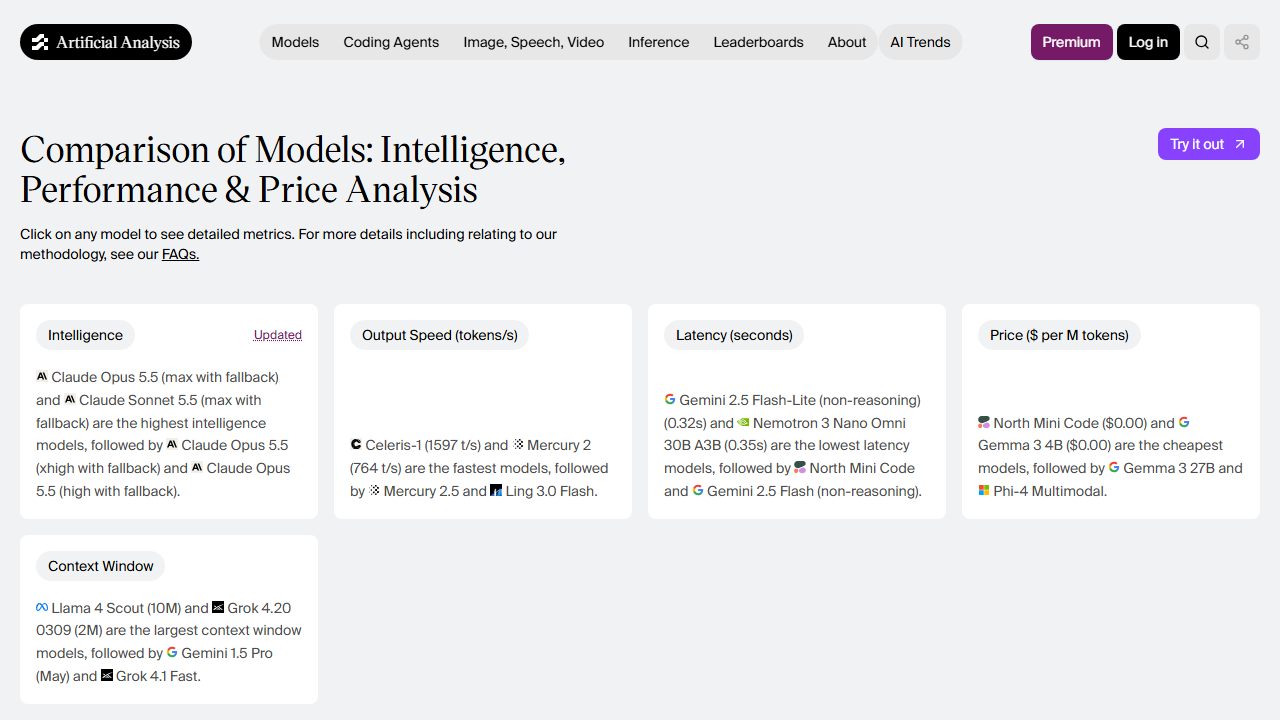
Comparison and analysis of AI models across key performance metrics including quality, price, output speed, latency, context window & others.
We measure real-world performance of coding agents on software engineering tasks, including cost, token usage, and execution time. We compare how performance changes across agents, models, and execution settings.
Humanity's Last Exam Dataset
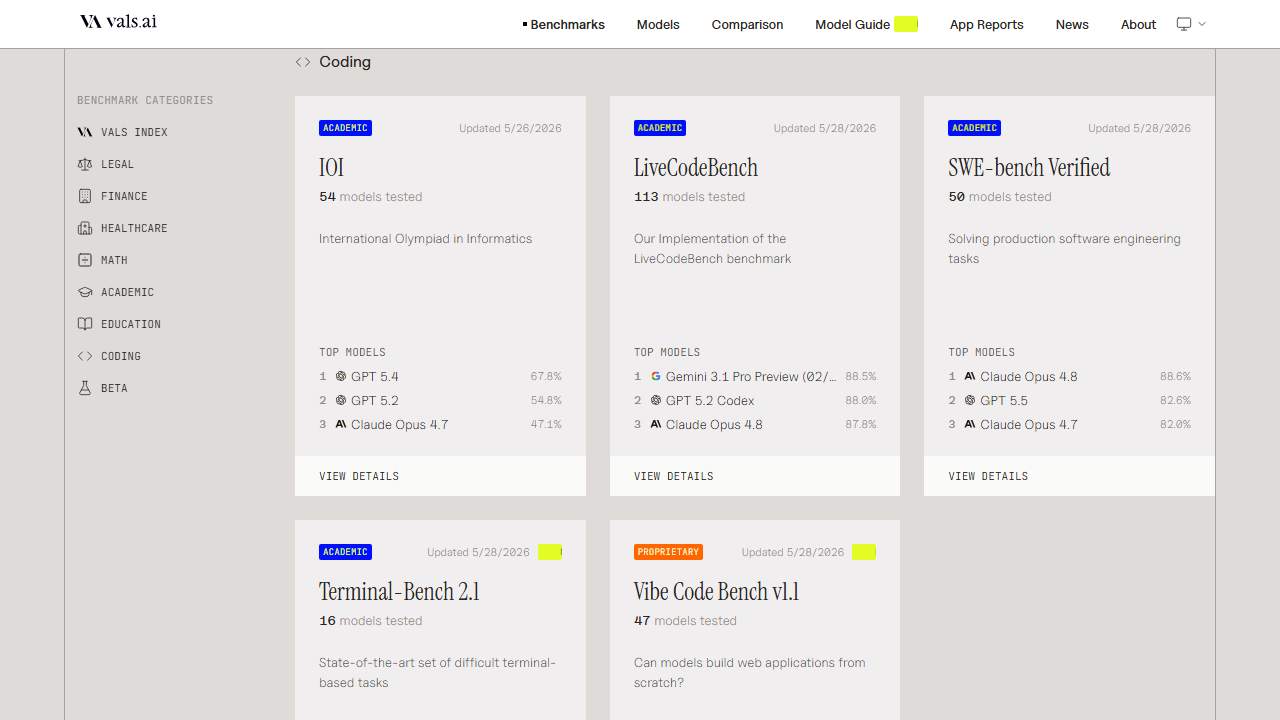
Vals AI evaluates models on the real tasks each industry relies on, with public leaderboards and benchmark methodology.
Explore leaderboards with expert-driven LLM benchmarks and updated AI model rankings across coding, reasoning and more.
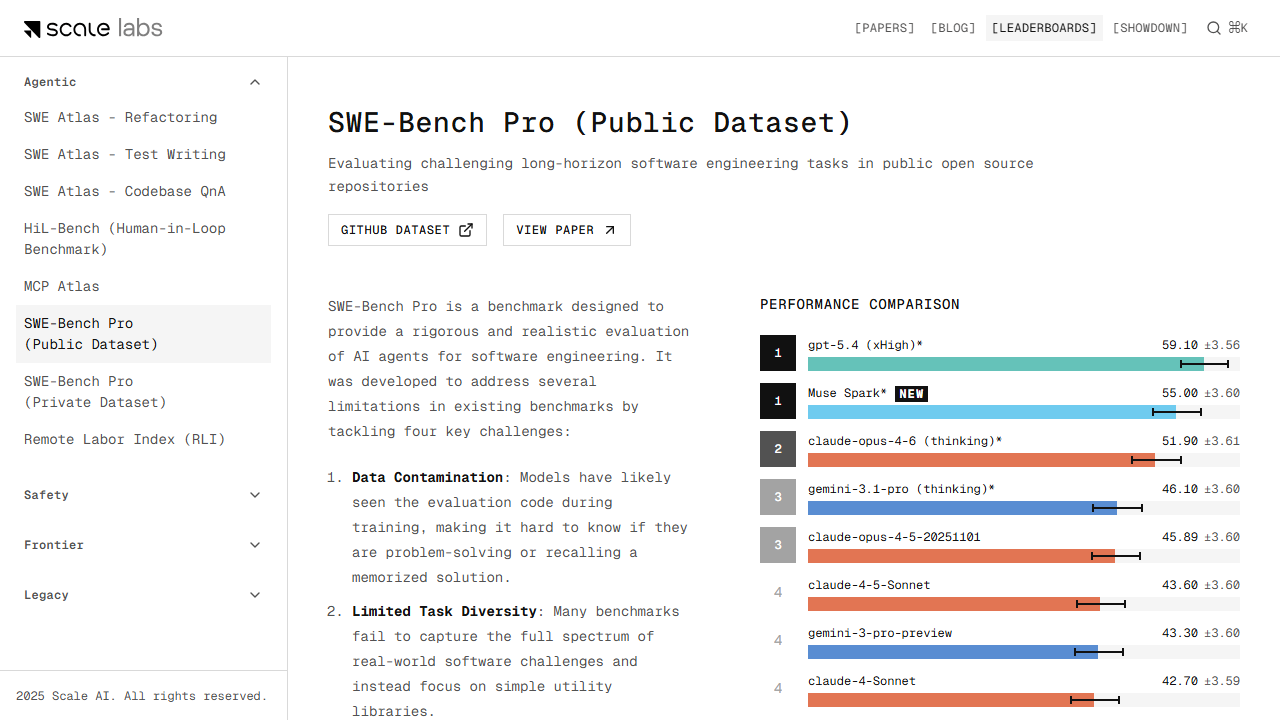
Compare the resolve rates of GPT-5.4, Muse Spark, Claude Opus 4.6, and Gemini 3.1 Pro on SWE-Bench Pro.
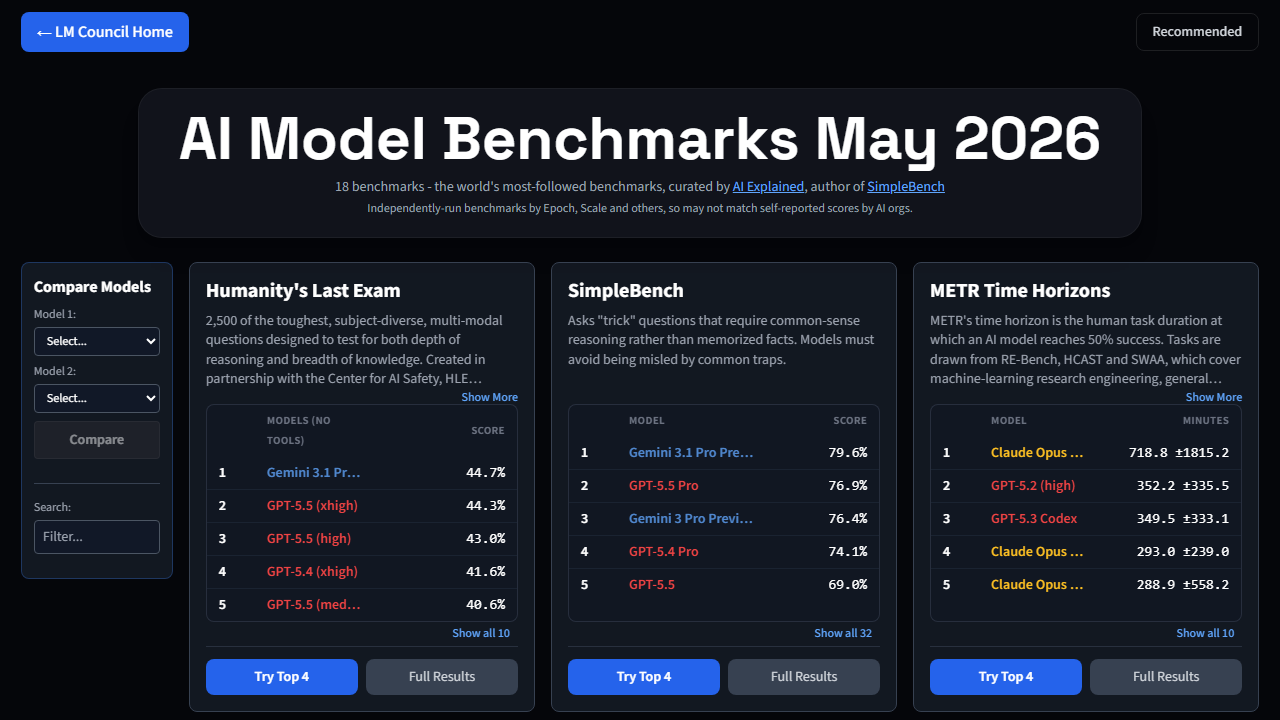
Compare GPT-5.6, Claude Fable 5, Claude Opus 5, Gemini 3, and other frontier models across Humanity's Last Exam, FrontierMath, GPQA, SWE-bench, and more. Every result snapshot links its source and checked date.
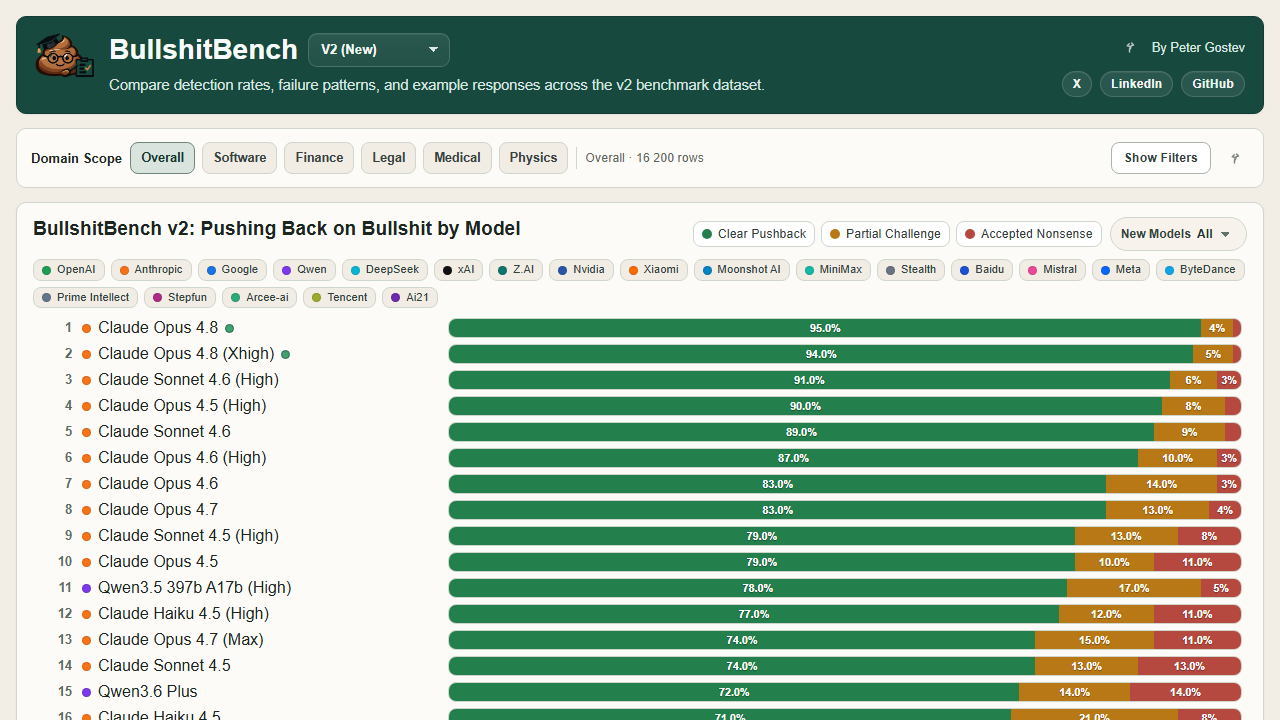
Compare how AI models respond to nonsense: clear pushback, partial challenge, or accepting a broken premise.
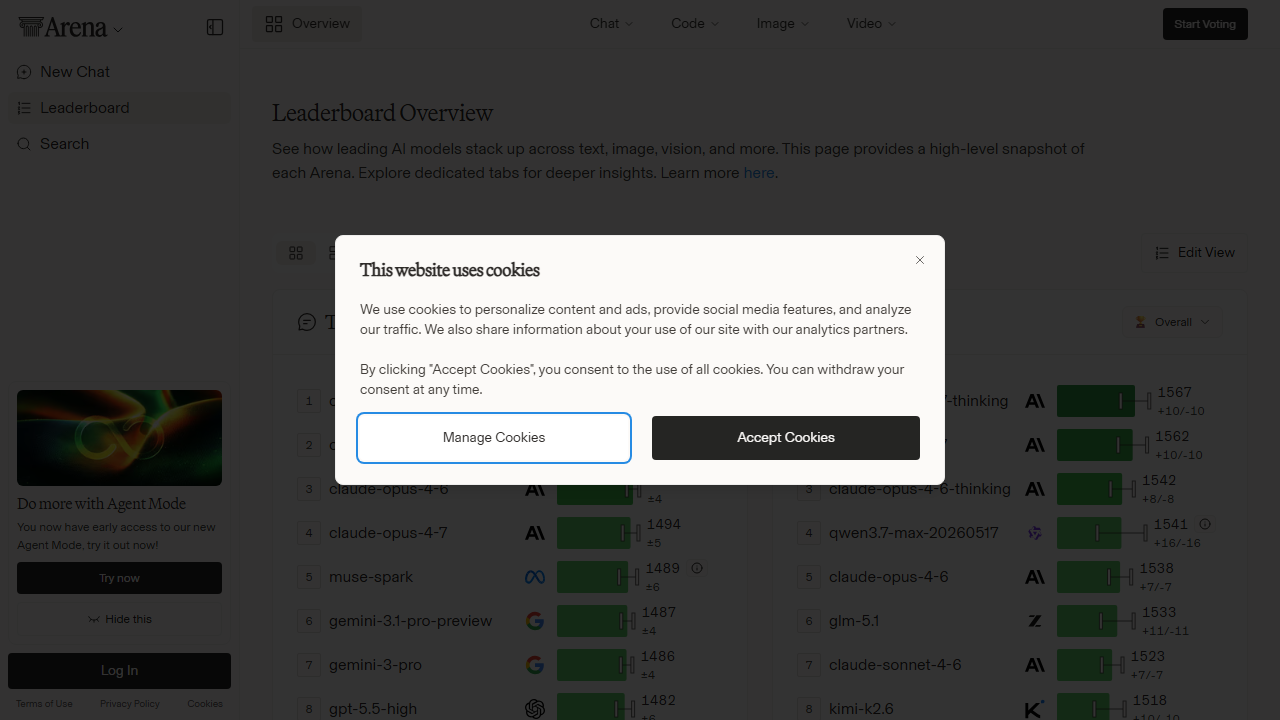
See how leading AI models stack up across text, image, vision, and more. This page provides a high-level snapshot of each Arena. Explore dedicated tabs for deeper insights.
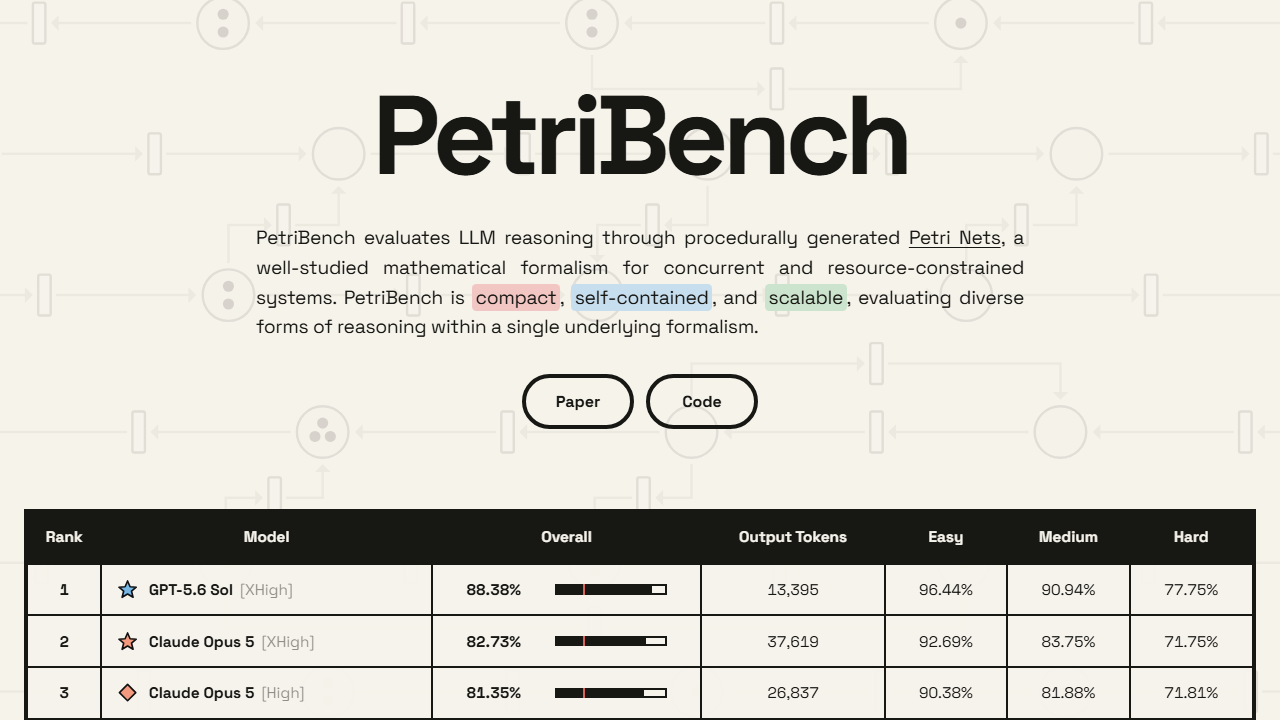
A benchmark for evaluating LLM reasoning over Petri nets.
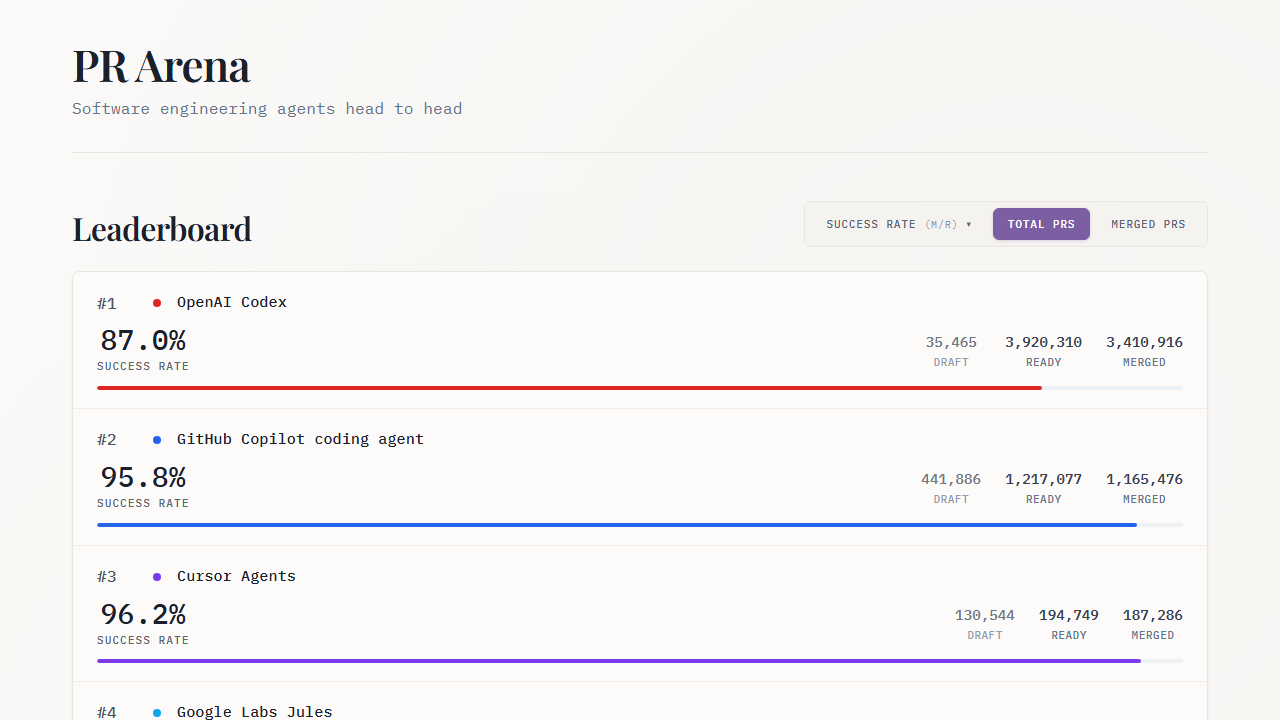
Explore benchmark and evaluation details from prarena.ai in a focused external resource.
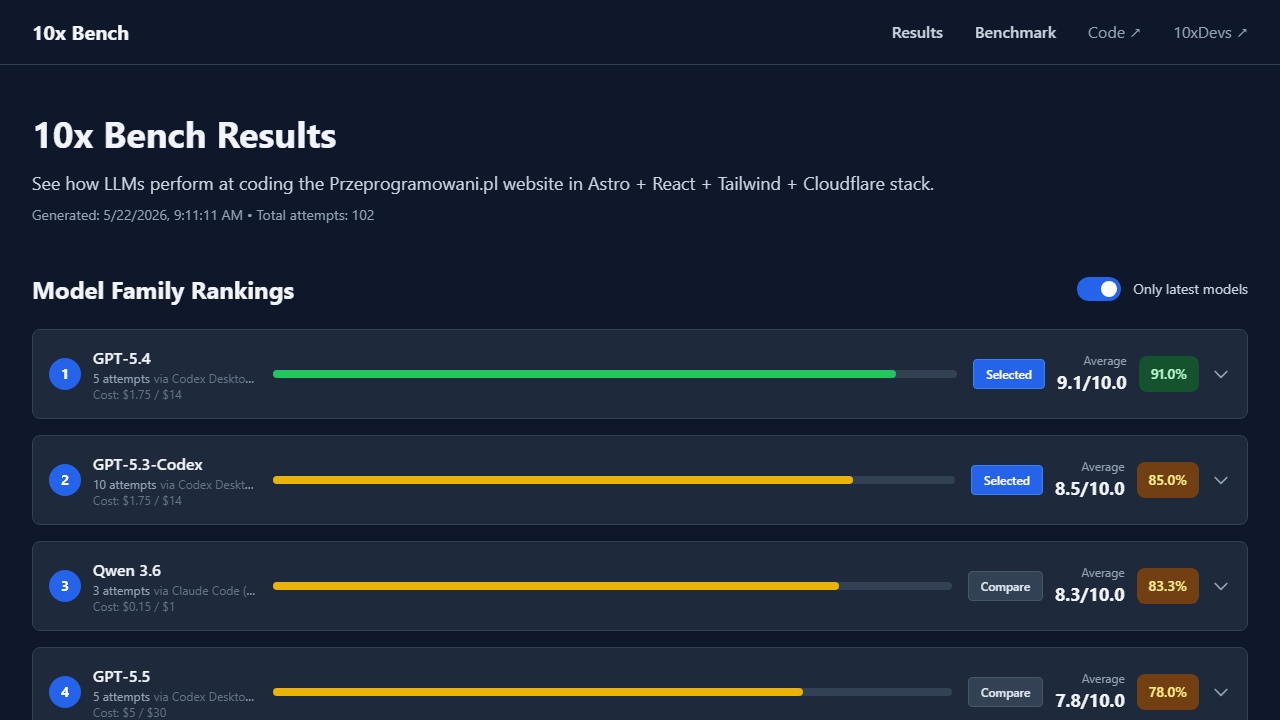
See how leading LLMs perform when each gets a single shot at building a real production website in Astro, React, Tailwind and Cloudflare. Compare scores, screenshots and generated code side by side.
Explore benchmark and evaluation details from bridgebench.ai in a focused external resource.